<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://hbunyamin.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://hbunyamin.github.io/" rel="alternate" type="text/html" /><updated>2026-08-07T01:32:09+00:00</updated><id>https://hbunyamin.github.io/feed.xml</id><title type="html">Hendra Bunyamin</title><subtitle>Hendra Bunyamin&apos;s academic portfolio</subtitle><author><name>Hendra Bunyamin</name><email>hendra.bunyamin@it.maranatha.edu</email></author><entry><title type="html">[EN] Completing the Square for Normal Model with Multiple Observations</title><link href="https://hbunyamin.github.io/data-science-2/Completing_the_Square_for_Multivariate_Model/" rel="alternate" type="text/html" title="[EN] Completing the Square for Normal Model with Multiple Observations" /><published>2021-04-12T00:00:00+00:00</published><updated>2021-04-12T00:00:00+00:00</updated><id>https://hbunyamin.github.io/data-science-2/Completing_the_Square_for_Normal_Model</id><content type="html" xml:base="https://hbunyamin.github.io/data-science-2/Completing_the_Square_for_Multivariate_Model/"><![CDATA[<p>The subchapter 2.5 of <a href="http://www.stat.columbia.edu/~gelman/book/BDA3.pdf"><strong>Bayesian Data Analysis Third Edition</strong></a> explains how to estimate a normal mean with known variance; particularly, the subchapter extends the development of a normal model with a single observation into the more realistic situation where <em>a sample of independent and identically distributed observations</em> \(y = (y_1, \ldots, y_n)\) are available.</p>

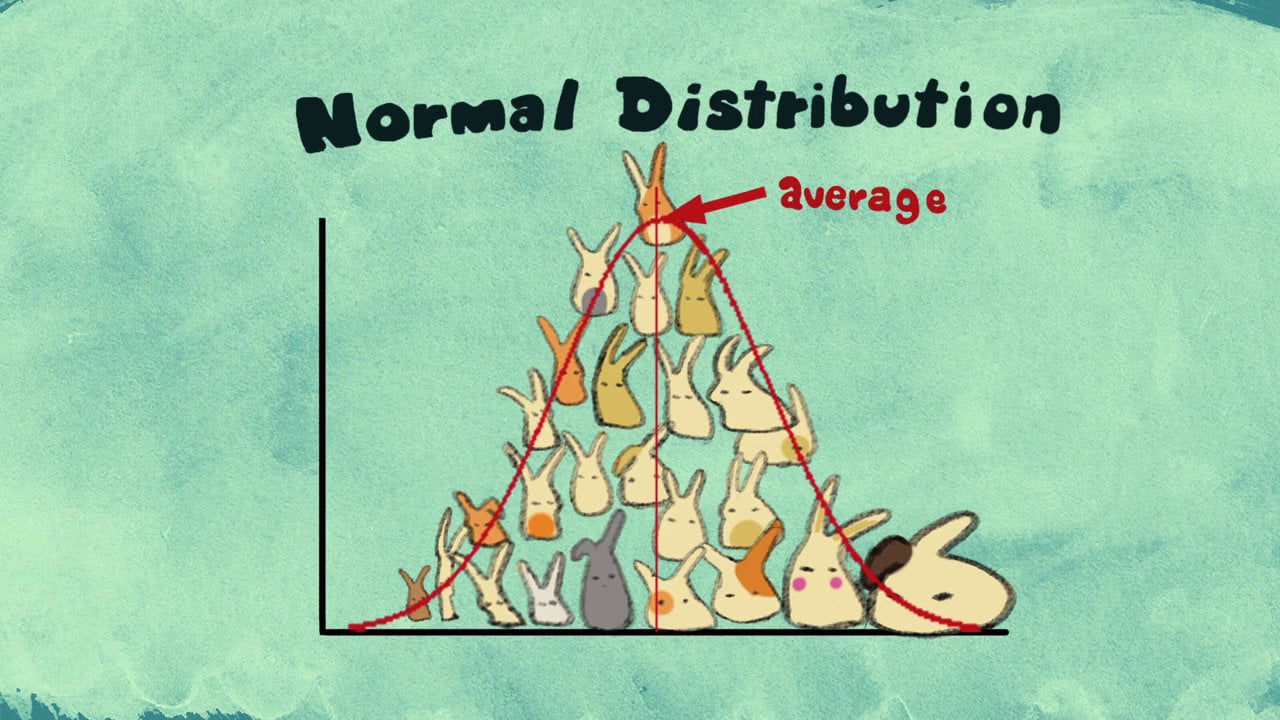
<p><a href="/assets/images/normal-dist.jpg"><img src="/assets/images/normal-dist.jpg" alt="img1" class="img-responsive" /></a>      <br />
\(\pmb{\text{Figure 1}}\): Example of a normal distribution consisting a horde of rabbits. Image taken from <a href="https://vimeo.com/75089338">Casey Dunn</a>, some rights reserved.</p>

<p>The <em>posterior</em> density of the normal model consists of a <em>likelihood</em> distribution, \(\Pr(y \mid \theta)\), and a <em>prior</em> distribution, \(\Pr(\theta)\). Specifically,</p>

\[\begin{align}
	y_i \mid \theta &amp;\sim \text{N}(\theta, \sigma^2) &amp;&amp; \text{A normal distribution with mean = }\theta \text{ and variance = }\sigma^2\text{, for }i=1, \ldots, n \\
	\theta          &amp;\sim \text{N}(\mu_0, \tau_0^2)  &amp;&amp;  \text{A normal distribution with mean = }\mu_0 \text{ and variance = }\tau_0^2.
\end{align}\]

<p>Proceeding formally, the posterior density is</p>

<p>\(\begin{align}
\Pr(\theta \mid y) &amp;\propto \Pr(\theta) \Pr(y \mid \theta) &amp;&amp; \text{posterior definition} \tag{1}\label{eq:definition}\\
                   &amp;= \Pr(\theta) \prod_{i=1}^{n} \Pr(y_i \mid \theta) &amp;&amp; \text{i.i.d observations} \tag{2}\label{eq:iid} \\
                   &amp;\propto \exp \left( -\frac{1}{2 \tau_0^2} (\theta - \mu_0)^2 \right) \prod_{i=1}^n \exp \left( - \frac{1}{2 \sigma^2} (y_i - \theta)^2 \right) &amp;&amp; \text{normal distributions} \tag{3}\label{eq:exposition-normal} \\
                   &amp;= \exp \left( -\frac{1}{2} \left( \frac{1}{\tau_0^2} (\theta - \mu_0)^2 + \frac{1}{\sigma^2} \sum_{i=1}^{n} (y_i - \theta)^2 \right) \right)  &amp;&amp; \text{sum all terms} \tag{4}\label{eq:sum-all-terms} \\
                   &amp;= \exp \left( -\frac{1}{2} \left( \frac{1}{\tau_0^2} \theta^2 - \frac{2 \theta \mu_0}{\tau_0^2} + \frac{\mu_0^2}{\tau_0^2} + \frac{1}{\sigma^2} \sum_{i=1}^n (y_i^2 - 2 \theta y_i + \theta^2) \right) \right) &amp;&amp; \text{expand all squares} \tag{5}\label{eq:expand-all} \\
                   &amp;= \exp \left( -\frac{1}{2} \left( \frac{1}{\tau_0^2} \theta^2 - \frac{2 \theta \mu_0}{\tau_0^2} + \frac{\mu_0^2}{\tau_0^2} + \frac{\sum_{i=1}^n y_i^2}{\sigma^2} - \frac{2 \theta \sum_{i=1}^n y_i}{\sigma^2} + \frac{n \theta^2}{\sigma^2} \right) \right) &amp;&amp; \text{expand the last term} \tag{6}\label{eq:expand-again} \\
                   &amp;= \exp \left( -\frac{1}{2} \left( \frac{\theta^2}{\tau_0^2} + \frac{n \theta^2}{\sigma^2} - 2 \theta \left( \frac{\mu_0}{\tau_0^2} + \frac{\sum_{i=1}^n y_i}{\sigma^2} \right) + \frac{\mu_0^2}{\tau_0^2} + \frac{\sum_{i=1}^n y_i^2}{\sigma^2} \right) \right) &amp;&amp; \text{group all }\theta s \text{ &amp; } \theta^2 s \tag{7}\label{eq:collect-all} \\
                   &amp;= \exp \left( -\frac{1}{2} \left( \theta^2 \left( \frac{1}{\tau_0^2} + \frac{n}{\sigma^2} \right) - 2 \theta \left( \frac{\mu_0}{\tau_0^2} + \frac{\sum_{i=1}^n y_i}{\sigma^2} \right) + \frac{\mu_0^2}{\tau_0^2} + \frac{\sum_{i=1}^n y_i^2}{\sigma^2} \right) \times \frac{\frac{1}{\frac{1}{\tau_0^2} + \frac{n}{\sigma^2}}}{\frac{1}{\frac{1}{\tau_0^2} + \frac{n}{\sigma^2}}} \right) &amp;&amp; \text{use a trick} \tag{8}\label{eq:multiply-by} \\
                   &amp;= \exp \left( - \frac{1}{2} \frac{  \left( \theta^2 - 2 \theta \frac{ \frac{\mu_0}{\tau_0^2} + \frac{\sum y_i}{\sigma^2}}{ \frac{1}{\tau_0^2} + \frac{n}{\sigma^2}} + \frac{\frac{\mu_0^2}{\tau_0^2}}{\frac{1}{\tau_0^2} + \frac{n}{\sigma^2}}  + \frac{\frac{\sum y_i^2}{\sigma^2}}{\frac{1}{\tau_0^2} + \frac{n}{\sigma^2}} \right)  }{\frac{1}{\frac{1}{\tau_0^2} + \frac{n}{\sigma^2}}} \right) \tag{9}\label{eq:atas-bawah} \\
                   &amp;= \exp \left( - \frac{1}{2} \frac{\left( \theta - \frac{\frac{\mu_0}{\tau_0^2} + \frac{\sum y_i}{\sigma^2} }{ \frac{1}{\tau_0^2} + \frac{n}{\sigma^2}  }  \right)^2 + C}{\frac{1}{\frac{1}{\tau_0^2} + \frac{n}{\sigma^2}}}   \right) &amp;&amp; \text{with }C \text{ is a constant} \tag{10}\label{eq:a-constant} \\
                   &amp;\propto \exp \left( -\frac{1}{2} \frac{(\theta - \mu_n)^2}{\tau_n^2} \right) \tag{10}\label{eq:almost} \\
                   &amp;\propto \text{N}(\mu_n, \tau_n^2)  &amp;&amp; \text{a normal distribution}        \tag{11}\label{eq:finally}         
\end{align}\)
with</p>

<p>\(\begin{align}
	\mu_n &amp;= \frac{\frac{\mu_0}{\tau_0^2} + \frac{\sum_{i=1}^n y_i}{\sigma^2}}{\frac{1}{\tau_0^2} + \frac{n}{\sigma^2} } \tag{12}\label{eq:mu-n} \\
	      &amp;= \frac{\frac{\mu_0}{\tau_0^2} + \frac{n \bar{y}}{\sigma^2}}{\frac{1}{\tau_0^2} + \frac{n}{\sigma^2} } &amp;&amp; \text{because }\bar{y} = \frac{\sum_{i=1}^n y_i}{n} \tag{13}\label{eq:mu-n-2}
\end{align}\)
and</p>

\[\begin{equation}
	\frac{1}{\tau_n^2} = \frac{1}{\tau_0^2} + \frac{n}{\sigma^2}. \tag{14}\label{eq:sigma-n}
\end{equation}\]

<p>At last, we have shown that the <em>posterior</em> distribution of the normal model is also a normal distribution as it is explained by Equation (2.11) and (2.12) on page 42 of the <a href="http://www.stat.columbia.edu/~gelman/book/BDA3.pdf"><strong>book</strong></a>.</p>]]></content><author><name>Hendra Bunyamin</name><email>hendra.bunyamin@it.maranatha.edu</email></author><category term="probability" /><category term="statistics" /><summary type="html"><![CDATA[This article explains friendly steps to complete the square of normal distribution]]></summary></entry><entry><title type="html">[EN] A Quantum of the Fisher Information Derivation</title><link href="https://hbunyamin.github.io/data-science-1/Fisher_Information/" rel="alternate" type="text/html" title="[EN] A Quantum of the Fisher Information Derivation" /><published>2021-02-23T00:00:00+00:00</published><updated>2021-02-23T00:00:00+00:00</updated><id>https://hbunyamin.github.io/data-science-1/Fisher_Information</id><content type="html" xml:base="https://hbunyamin.github.io/data-science-1/Fisher_Information/"><![CDATA[<p>This post elaborates a derivation of Equation (2.20) on page 53 of <a href="http://www.stat.columbia.edu/~gelman/book/BDA3.pdf"><strong>Bayesian Data Analysis Third Edition</strong></a>.</p>

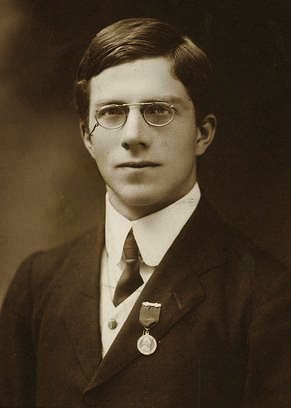
<p><a href="/assets/images/Youngronaldfisher2.JPG"><img src="/assets/images/Youngronaldfisher2.JPG" alt="img1" class="img-responsive" /></a>       <br />
\(\pmb{\text{Figure 1}}\): Sir Ronald Aylmer Fisher (17 February 1890 - 29 July 1962). One of his many great contributions to Statistics is <a href="https://en.wikipedia.org/wiki/Fisher_information">Fisher Information</a>. Image taken from <a href="https://en.wikipedia.org/wiki/Ronald_Fisher">Wikipedia</a>, some rights reserved.</p>

<p>Concretely, we want to show the derivation \(J(\theta)\), the <em>Fisher Information</em>, from</p>

\[\begin{equation}
	J(\theta) = \text{E}\left( \left( \frac{d \log \Pr(y \mid \theta )}{d\theta} \right)^2 \, \middle| \, \theta \right) \tag{1}\label{eq:start-point}
\end{equation}\]

<p>to</p>

\[\begin{equation}
	J(\theta) = - \text{E}\left( \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2} \, \middle| \, \theta \right). \tag{2}\label{eq:end-point}
\end{equation}\]

<p>The idea of this derivation comes from a <a href="https://web.stanford.edu/class/stats311/Lectures/lec-09.pdf"><strong>lecture note by John Duchi from Stanford Statistics class</strong></a>. The difference between this post and the lecture note is that the lecture note deals with <em>multi-variables</em> which employs second derivatives for multi-values (<a href="https://en.wikipedia.org/wiki/Hessian_matrix"><em>Hessian matrix</em></a>); on the other hand, this post deals with a single variable and employs a second derivative for just one value.</p>

<p>Let’s start with computing 
\(\begin{equation} 
	\text{E} \left( \frac{d \log \Pr(y \mid \theta)}{d\theta} \, \middle| \, \theta \right)
\end{equation}\).</p>

\[\require{cancel} \begin{align}
	\text{E}\left( \frac{d \log \Pr(y \mid \theta)}{d\theta} \, \middle| \, \theta \right) &amp;= \int \frac{d \log \Pr(y \mid \theta)}{d\theta} \Pr(y \mid \theta) d\theta  &amp;&amp; \text{definition of expectation} \tag{3}\label{eq:dlog-1} \\
	&amp;= \int \frac{d \Pr(y \mid \theta)}{d\theta} \frac{1}{\Pr(y \mid \theta)} \; \Pr(y \mid \theta) d\theta  &amp;&amp; \text{derivation of }\frac{d \log \Pr(y \mid \theta)}{d\theta} \tag{4}\label{eq:dlog-2} \\
	&amp;= \int \frac{d \Pr(y \mid \theta)}{d\theta} \frac{1}{\cancel{\Pr(y \mid \theta)}} \; \cancel{\Pr(y \mid \theta)}  d\theta \tag{5}\label{eq:dlog-3}	 \\
	&amp;= \int \frac{d \Pr(y \mid \theta)}{d\theta} d\theta  \tag{6}\label{eq:dlog-4}	 \\
	&amp;= \frac{d}{d\theta} \int \Pr(y \mid \theta) d\theta &amp;&amp; \text{exchange }\frac{d}{d\theta} \text{ and } \int \tag{7}\label{eq:dlog-5} \\
	&amp;= \frac{d}{d\theta} \underbrace{\int \Pr(y \mid \theta) d\theta}_{1} &amp;&amp; \text{property of a pdf}\tag{8}\label{eq:dlog-6} \\
	&amp;= \frac{d}{d\theta} (1) \tag{9}\label{eq:dlog-7} 	\\
	&amp;= 0. \tag{10}\label{eq:dlog-8}
\end{align}\]

<p>Consider Equation \eqref{eq:dlog-5}, we shall utilize this exchangeability between <em>integral</em> and <em>differentiation</em> again later.</p>

<p>Equation \eqref{eq:dlog-2} states that</p>

\[\begin{equation}
	\frac{d \log \Pr(y \mid \theta)}{d\theta} = \underbrace{\frac{1}{\Pr(y \mid \theta)}}_{u}  \underbrace{\frac{d \Pr(y \mid \theta)}{d\theta}}_{v}. \tag{11}\label{eq:first-order-derivation}
\end{equation}\]

<p>Therefore,</p>

\[\begin{align}
	\frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2} &amp;= \underbrace{- \frac{1}{\Pr( y \mid \theta )^2} \frac{d \Pr(y \mid \theta)}{d\theta}}_{u^{\prime}} \underbrace{\frac{d \Pr(y \mid \theta)}{d\theta}}_{v}  + \underbrace{\frac{1}{\Pr(y \mid \theta)}}_{u} \underbrace{\frac{d^2 \Pr(y \mid \theta)}{d\theta^2}}_{v^{\prime}} &amp;&amp;  \text{based on } u^{\prime} v + u v^{\prime} \tag{12}\label{eq:second-order-1} \\
	&amp;= \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} \frac{1}{\Pr(y \mid \theta)} - \left( \frac{d\Pr(y \mid \theta)}{d\theta} \frac{1}{\Pr(y \mid \theta)}  \right) \left( \frac{d\Pr(y \mid \theta)}{d\theta} \frac{1}{\Pr(y \mid \theta)}  \right) &amp;&amp; \text{just rearranging} \tag{13}\label{eq:second-order-2} \\
	&amp;= \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} \frac{1}{\Pr(y \mid \theta)} - \left(  \frac{d \log \Pr( y \mid \theta)}{d\theta} \right) \left( \frac{d \log \Pr( y \mid \theta)}{d\theta} \right) &amp;&amp; \text{based on Equation }\eqref{eq:first-order-derivation} \tag{14}\label{eq:second-order-3} \\	
	&amp;= \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} \frac{1}{\Pr(y \mid \theta)} - \left(  \frac{d \log \Pr( y \mid \theta)}{d\theta} \right)^{2} \tag{15}\label{eq:second-order-4}		
\end{align}\]

<p>From Equation \eqref{eq:second-order-4} we obtain</p>

\[\begin{align}
	\frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2} = \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} \frac{1}{\Pr(y \mid \theta)} - \left(  \frac{d \log \Pr( y \mid \theta)}{d\theta} \right)^{2} &amp;\Longleftrightarrow \left(  \frac{d \log \Pr( y \mid \theta)}{d\theta} \right)^{2} = - \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2} + \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} \frac{1}{\Pr(y \mid \theta)} \tag{16}\label{eq:second-order-last}
\end{align}\]

<p>Now we are ready to calculate
\(\begin{equation}
	\text{E}\left( \left( \frac{d \log \Pr(y \mid \theta )}{d\theta} \right)^2 \, \middle| \, \theta \right).
\end{equation}\)</p>

\[\require{cancel} \begin{align}
	\text{E}\left( \left( \frac{d \log \Pr(y \mid \theta )}{d\theta} \right)^2 \, \middle| \, \theta \right) &amp;= \int \left( \frac{d \log \Pr(y \mid \theta )}{d\theta} \right)^2 \Pr(y \mid \theta) d\theta &amp;&amp; \text{by definition} \tag{17}\label{eq:final-showdown-1}\\
	&amp;= \int \left( - \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2} + \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} \frac{1}{\Pr(y \mid \theta)} \right) \Pr(y \mid \theta) d\theta &amp;&amp; \text{by Equation }\eqref{eq:second-order-last} \tag{18}\label{eq:final-showdown-2}\\
	&amp;= \int \left( - \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2}  \right) \Pr(y \mid \theta) d\theta + \int \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} \frac{1}{\Pr(y \mid \theta)} \Pr(y \mid \theta) d\theta &amp;&amp; \text{by distributive} \tag{19}\label{eq:final-showdown-3}\\
	&amp;= \int \left( - \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2}  \right) \Pr(y \mid \theta) d\theta + \int \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} \frac{1}{\cancel{\Pr(y \mid \theta)}} \cancel{\Pr(y \mid \theta)} d\theta  \tag{20}\label{eq:final-showdown-4}\\		
	&amp;= \int \left( - \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2}  \right) \Pr(y \mid \theta) d\theta + \int \frac{d^2 \Pr(y \mid \theta)}{d\theta^2} d\theta  \tag{21}\label{eq:final-showdown-5}\\
	&amp;= \int \left( - \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2}  \right) \Pr(y \mid \theta) d\theta + \frac{d^2}{d\theta^2} \left( \int \Pr(y \mid \theta) d\theta \right) &amp;&amp; \text{by exchangeability again}  \tag{22}\label{eq:final-showdown-6}\\	
	&amp;= \int \left( - \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2}  \right) \Pr(y \mid \theta) d\theta + \underbrace{\frac{d^2}{d\theta^2} \left( \int \Pr(y \mid \theta) d\theta \right)}_{0} &amp;&amp; \text{similar to Equation }\eqref{eq:dlog-8}  \tag{23}\label{eq:final-showdown-7}\\					
	&amp;= \int \left( - \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2}  \right) \Pr(y \mid \theta) d\theta \tag{24}\label{eq:final-showdown-8}\\
	&amp;= - \int \left( \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2}  \right) \Pr(y \mid \theta) d\theta \tag{25}\label{eq:final-showdown-9}\\											
	&amp;= - \text{E}\left( \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2} \, \middle| \, \theta  \right). &amp;&amp; \text{by definition} \tag{26}\label{eq:final-showdown-10}					
\end{align}\]

<p>At last, we have finally shown that</p>

\[\begin{equation}
	J(\theta) = \text{E}\left( \left( \frac{d \log \Pr(y \mid \theta )}{d\theta} \right)^2 \, \middle| \, \theta \right)  = - \text{E}\left( \frac{d^2 \log \Pr(y \mid \theta)}{d\theta^2} \, \middle| \, \theta \right)
\end{equation}\]

<p>as it is explained by Equation (2.20) on page 53 of the <a href="http://www.stat.columbia.edu/~gelman/book/BDA3.pdf"><strong>book</strong></a>.</p>]]></content><author><name>Hendra Bunyamin</name><email>hendra.bunyamin@it.maranatha.edu</email></author><category term="data analysis" /><category term="probability" /><category term="statistics" /><summary type="html"><![CDATA[This article explains the equation (2.20) from Bayesian Data Analysis on page 53]]></summary></entry><entry><title type="html">[EN] Variance and Covariance of Categorical Distribution</title><link href="https://hbunyamin.github.io/ml-2/Expectation_Variance_and_Covariance_of_Categorical_Distribution/" rel="alternate" type="text/html" title="[EN] Variance and Covariance of Categorical Distribution" /><published>2020-09-18T00:00:00+00:00</published><updated>2020-09-18T00:00:00+00:00</updated><id>https://hbunyamin.github.io/ml-2/Expectation_Variance_and_Covariance_of_Categorical_Distribution</id><content type="html" xml:base="https://hbunyamin.github.io/ml-2/Expectation_Variance_and_Covariance_of_Categorical_Distribution/"><![CDATA[<p>This post is inspired by <a href="http://www.cs.columbia.edu/~blei/fogm/2020F/index.html">the lecture given by David Blei</a> on Thursday, 17 September 2020. One of the topics he explained was related to a <strong><em>categorical variable</em></strong> and a <strong><em>categorical distribution</em></strong>. This post will elaborate those two concepts. Let’s get started.</p>

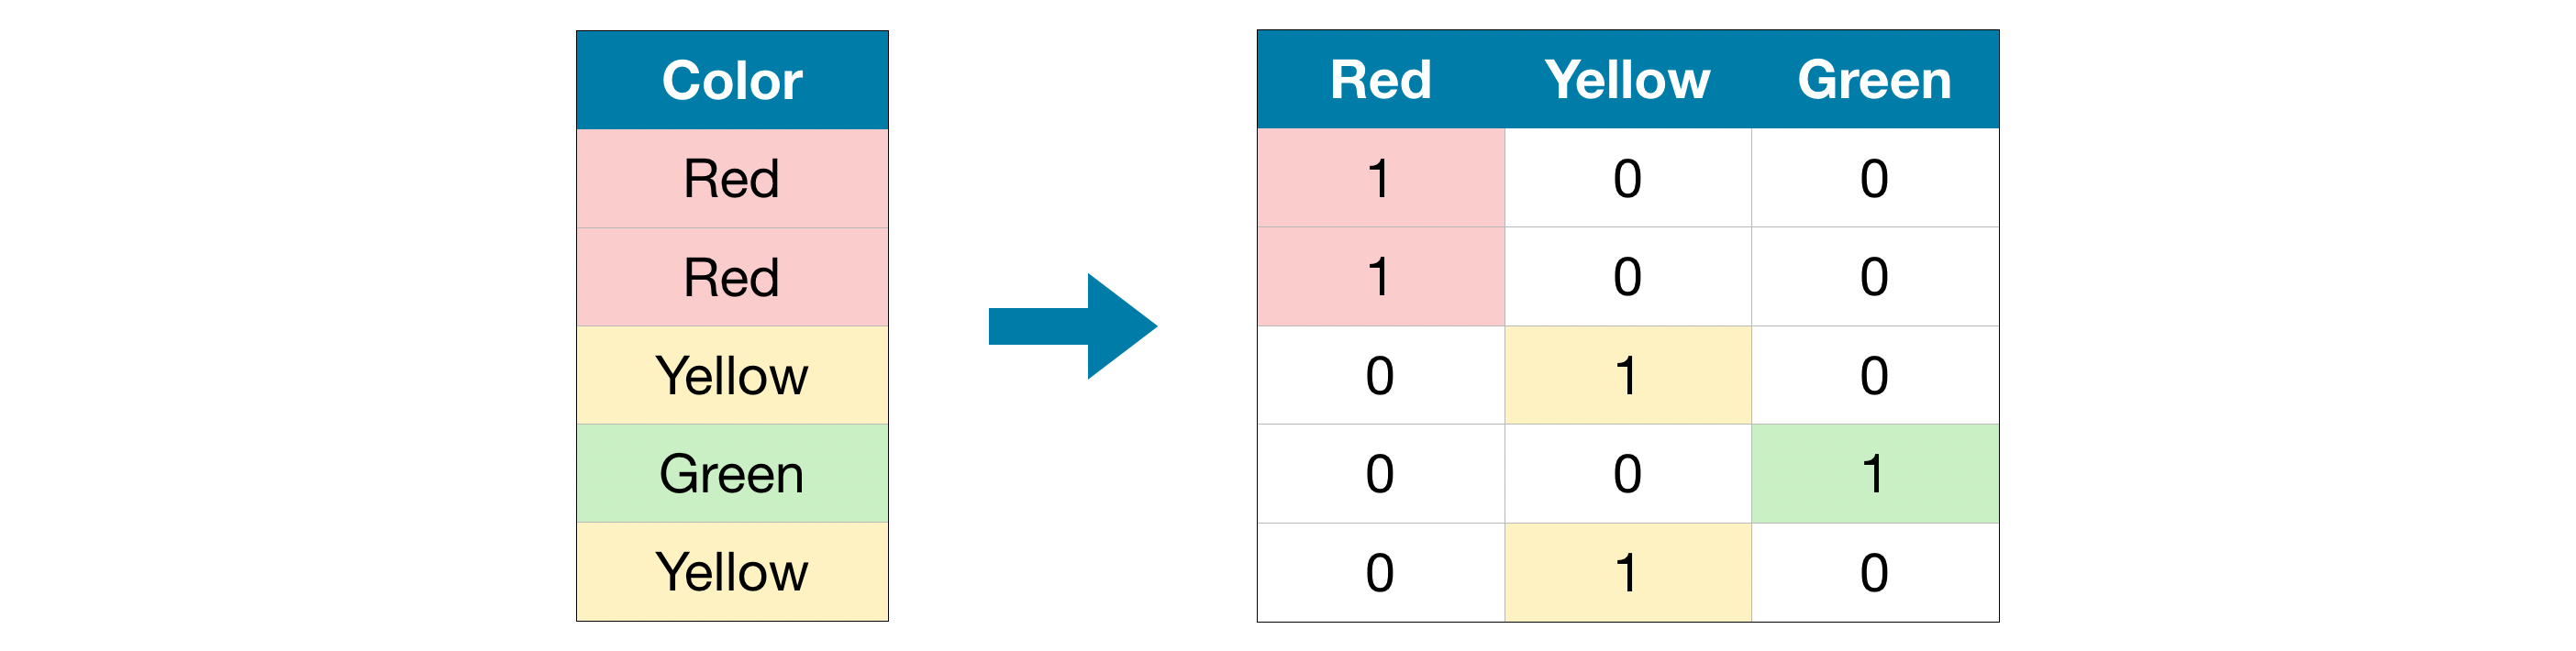
<p><a href="/assets/images/one-hot-encoding.png"><img src="/assets/images/one-hot-encoding.png" alt="img1" class="img-responsive" /></a> \( \pmb{\text{Figure 1}} \) : A categorical variable ( \( \text{Color} \)) and its values ( \( \text{Red} \), \( \text{Yellow} \), and \( \text{Green} \) ). Image taken from <a href="https://www.kaggle.com/alexisbcook/categorical-variables">Kaggle</a>, some rights reserved.</p>

<p>\(\text{Figure 1}\) shows an example of categorical values stored in a categorical variable, \(\text{Color}\). Basically, a categorical variable takes one of \(K\) values and each categorical value is represented by a \(K\)-vector with a single \(1\) and otherwise \(0\)s.</p>

<blockquote>
  <p>Let’s denote a categorical variable as \(x^{(k)}\) which means that the \(k\)th component of it has a a single \(1\) and otherwise \(0\)s.</p>
</blockquote>

<p>For example, the categorical variable in \(\text{Figure 1}\) has \(3\) values ( \(\text{Red}\), \(\text{Yellow}\), and \(\text{Green}\) ) and each value  is represented by \(3\)-vector with a single \(1\) and otherwise \(0\)s as follows:</p>

\[\begin{align}
    \text{Red} &amp;= x^{(1)} = (1, 0, 0 ) \\
    \text{Yellow} &amp;= x^{(2)} =  (0, 1, 0 ) \tag{1}\label{eq:yellow} \\    
    \text{Green} &amp;= x^{(3)} = (0, 0, 1 ).
  \end{align}\]

<p>The \(K\)-vector with single \(1\) and otherwise \(0\)s is commonly named <a href="https://machinelearningmastery.com/why-one-hot-encode-data-in-machine-learning/"><strong>one-hot vector</strong></a>.</p>

<p>A <strong><em>categorical distribution</em></strong> is parameterized by \(\theta\). Moreover, \(\pmb{\theta}\) <strong>specifies the probability of each categorical value</strong>. Suppose we have \(K\) categorical values; therefore,</p>

\[\begin{equation}
\theta = (\theta_1, \theta_2, \ldots, \theta_K) \tag{2}\label{eq:theta}
\end{equation}\]

<p>with</p>

\[\begin{equation}
  \sum_{k=1}^{K}{\theta_k} = 1 \text{ and } 0 \leq \theta_k \leq 1 \text{ for }k=1, \ldots, K. \tag{3}\label{eq:theta-constraints}
\end{equation}\]

<p>Consider that \(X^{(k)}\) is a random <em>categorical</em> variable which takes one of \(K\) values. Moreover, since \(X^{(k)}\) is random variable, it has <strong><em>categorical distribution</em></strong> that is described by a discrete probability distribution,</p>

<p>\(\begin{equation}
  \text{p}(x^{(k)}) = \prod_{l=1}^{K}{\theta_{l}^{x^{(l)}}} \tag{4}\label{eq:pdf-categorical}
\end{equation}\)<br />
with \(x^{(l)}\) is the \(l\)th component of \(x^{(k)}\). Additionally, we elaborate Equation \eqref{eq:pdf-categorical} into</p>

\[\begin{align}
  \text{p}(x^{(k)}) &amp;= \prod_{l=1}^{K}{\theta_{l}^{x^{(l)}}} \\
                             &amp;= \theta_{1}^{x^{(1)}} \times \theta_{2}^{x^{(2)}} \times \cdots \times \theta_{k}^{x^{(k)}} \times \cdots \times \theta_{K}^{x^{(K)}}   \\
                             &amp;= \theta_{1}^{0} \times \theta_{2}^{0} \times \cdots \times \theta_{k}^{1} \times \cdots \times \theta_{K}^{0} \\
                             &amp;= \theta_{k}. \tag{5}\label{eq:pdf-categorical-simplified}
\end{align}\]

<p>Let’s put Equation \eqref{eq:pdf-categorical-simplified} into practice and demonstrate it in one example. Suppose we want to compute \(\text{p}(\text{Yellow})\) in Equation \eqref{eq:yellow},</p>

\[\begin{align}
  \text{p}(\text{Yellow}) &amp;= \text{p}(x^{(2)}) \\
                            &amp;= \text{p}((0,1,0)) &amp; \Rightarrow \text{1st} = 0, \text{2nd} = 1, \text{3rd} = 0 \\
                              &amp;= \prod_{l=1}^{3}{\theta_{l}^{x^{(l)}}} \\
                              &amp;= \theta_{1}^{x^{(1)}} \times \theta_{2}^{x^{(2)}} \times \theta_{3}^{x^{(3)}} \\
                              &amp;= \theta_{1}^{0} \times \theta_{2}^{1} \times \theta_{3}^{0} \\
                              &amp;= \theta_{2}.
\end{align}\]

<p>With Equation \eqref{eq:pdf-categorical-simplified} in hand, we are now ready to compute the <em>expectation</em> of \(X^{(k)}\) as</p>

\[\begin{align}
  \text{E}(X^{(k)}) &amp;= \sum_{l=1}^{K}{x^{(l)} \text{p}(x^{(l)})} \\
                    &amp;= \underbrace{0 \times \text{p}(x^{(1)})}_{1\text{st}} + \underbrace{0 \times \text{p}(x^{(2)})}_{2\text{nd}} + \cdots + \underbrace{1 \times \text{p}(x^{(k)})}_{k\text{th}} + \cdots + \underbrace{0 \times \text{p}(x^{(K)}}_{K\text{th}})  \\ 
                    &amp;= \text{p}(x^{(k)}) \\ 
                    &amp;= \theta_k. \tag{6}\label{eq:expectation}
\end{align}\]

<p>Next, we compute the Variance, \(\text{Var}\), as follows:</p>

\[\begin{align}
  \text{Var}(X^{(k)}) &amp;= \underbrace{\text{E}((X^{(k)})^2)}_{\text{Part I}} - \underbrace{(\text{E}(X^{(k)}))^2}_{\text{Part II}}. &amp; \text{the definition of variance} \tag{7}\label{eq:variance-definition} \\

\end{align}\]

<p>Next, we compute \(\text{Part I}\), \(\text{E}((X^{(k)})^2)\), as follows:</p>

\[\begin{align}
  \text{E}((X^{(k)})^2) &amp;= \sum_{l=1}^{K}{(x^{(l))^2} \text{p}(x^{(l)})} \\
                    &amp;= \underbrace{0^2 \times \text{p}(x^{(1)})}_{1\text{st}} + \underbrace{0^2 \times \text{p}(x^{(2)})}_{2\text{nd}} + \cdots + \underbrace{1^2 \times \text{p}(x^{(k)})}_{k\text{th}} + \cdots + \underbrace{0^2 \times \text{p}(x^{(K)}}_{K\text{th}})  \\ 
                    &amp;= \text{p}(x^{(k)}) \\ 
                    &amp;= \theta_k. \tag{8}\label{eq:expectation-x-square}
\end{align}\]

<p>Now, we can finalize computing the Variance in Equation \eqref{eq:variance-definition},</p>

\[\begin{align}
  \text{Var}(X^{(k)}) &amp;= \text{E}((X^{(k)})^2) - (\text{E}(X^{(k)}))^2 &amp;&amp; \text{by definition of variance} \\
                      &amp;= \theta_k - (\theta_k)^2 &amp;&amp; \text{using Equation }\eqref{eq:expectation} \text{ and }\eqref{eq:expectation-x-square}  \\
                      &amp;= \theta_k (1 - \theta_k). &amp;&amp; \text{using distributive property} \tag{9}\label{eq:variance}
\end{align}\]

<p>Last but not least, we shall compute the Covariance, \(\text{Cov}(X^{(j)}, X^{(k)})\). We start by the definition of Covariance,</p>

\[\begin{align}
  \text{Cov}(X^{(j)}, X^{(k)}) &amp;= \underbrace{\text{E}(X^{(j)} X^{(k)})}_{\text{Part I}} - \underbrace{(\text{E}(X^{(j)}) E(X^{(k)}))}_{\text{Part II}}. &amp;&amp; \text{by definition} \tag{10}\label{eq:covariance}                             
\end{align}\]

<p>Let’s compute the \(\text{Part I}\) as follows:</p>

\[\begin{align}
  \text{E}(X^{(j)} X^{(k)}) &amp;= (0)(0) \theta_1 + \cdots + \underbrace{(1)(0) \theta_j}_{j\text{th}} + \cdots + \underbrace{(0)(1) \theta_k}_{k\text{th}} + \cdots + (0)(0) \theta_K  \\
                            &amp;= 0. \tag{11}\label{eq:covariance-zero}
\end{align}\]

<p>Eventually, we can finalize Equation \eqref{eq:covariance} as</p>

\[\begin{align}
  \text{Cov}(X^{(j)}, X^{(k)}) &amp;= \text{E}(X^{(j)} X^{(k)}) - (\text{E}(X^{(j)}) E(X^{(k)})) \\
                               &amp;= 0 - \theta_j \theta_k &amp;&amp; \text{using Equation } \eqref{eq:expectation} \text{ and }\eqref{eq:covariance-zero} \\
                               &amp;= - \theta_j \theta_k.
\end{align}\]

<p>To conclude, we have shown how to derive the <strong><em>expectation</em></strong>, <strong><em>variance</em></strong>, and <strong><em>covariance</em></strong> of a <em>categorical distribution</em>. We hope this post helps anyone who wants to understand a <em>categorical distribution</em>.</p>]]></content><author><name>Hendra Bunyamin</name><email>hendra.bunyamin@it.maranatha.edu</email></author><category term="probability" /><category term="statistics" /><summary type="html"><![CDATA[This article discusses properties of categorical distribution]]></summary></entry><entry><title type="html">[ID] Contoh Pembuktian Ruang Vektor dengan sangat Detil</title><link href="https://hbunyamin.github.io/posts/2019/03/blog-post-5/" rel="alternate" type="text/html" title="[ID] Contoh Pembuktian Ruang Vektor dengan sangat Detil" /><published>2019-03-22T00:00:00+00:00</published><updated>2019-03-22T00:00:00+00:00</updated><id>https://hbunyamin.github.io/posts/2019/03/ruang-vektor</id><content type="html" xml:base="https://hbunyamin.github.io/posts/2019/03/blog-post-5/"><![CDATA[<p>Tunjukkan bahwa himpunan dari semua matriks berukuran \(2 \times 3\) beserta operasi <em>matrix addition</em> dan <em>scalar multiplication</em> merupakan sebuah <strong>ruang vektor</strong>.</p>

<p><strong>Bukti</strong>: <br />
Misalkan himpunan dari semua matriks berukuran \(2 \times 3\) beserta operasi <em>matrix addition</em> dan <em>scalar multiplication</em> adalah \(V\).</p>

<p>Diketahui juga \(A\), \(B\), dan \(C\) adalah matriks berukuran \(2 \times 3\) dan \(k\), \(l\) adalah skalar dengan spesifikasi sebagai berikut:</p>

<p>\(A = \begin{bmatrix}a_{11} &amp; a_{12} &amp; a_{13}\\a_{21} &amp; a_{22} &amp; a_{23}\end{bmatrix}\), \(B = \begin{bmatrix} 	b_{11} &amp; b_{12} &amp; b_{13} \\ b_{21} &amp; b_{22} &amp; b_{23}\end{bmatrix}\), dan \(C = \begin{bmatrix} 	c_{11} &amp; c_{12} &amp; c_{13} \\ c_{21} &amp; c_{22} &amp; c_{23} \end{bmatrix}\).</p>

<p><a href="https://www.amazon.com/Elementary-Linear-Algebra-Ron-Larson/dp/1305658000/">Larson</a> (2016) subbab 4.2 hlm. 161 menyatakan bahwa pembuktian suatu himpunan merupakan ruang vektor harus memenuhi 10 aksioma. Berikut akan dibuktikan untuk 10 aksioma tersebut.</p>
<ol>
  <li>Apakah \(A+B\) juga ada di dalam \(V\)?  <br />
Ya karena   <br />
\(\begin{align}
 A + B &amp;= \begin{bmatrix} a_{11} &amp; a_{12} &amp; a_{13} \\ a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} + \begin{bmatrix} 	b_{11} &amp; b_{12} &amp; b_{13} \\ b_{21} &amp; b_{22} &amp; b_{23} \end{bmatrix}  \\
       &amp;= \begin{bmatrix} 	a_{11}+b_{11} &amp; a_{12}+b_{12} &amp; a_{13}+b_{13} \\ a_{21}+b_{21} &amp; a_{22}+b_{22} &amp; a_{23}+b_{23}	 \end{bmatrix}.
\end{align}\)  <br />
<br />
\(\begin{bmatrix} a_{11}+b_{11} &amp; a_{12}+b_{12} &amp; a_{13}+b_{13} \\
 a_{21}+b_{21} &amp; a_{22}+b_{22} &amp; a_{23}+b_{23} \end{bmatrix}\) merupakan matriks berukuran \(2 \times 3\), berarti \(A+B\) juga ada di dalam \(V\).  <br />
<br /></li>
  <li>Apakah \(A+B = B+A\)?  <br />
Ya karena  <br />
\(\begin{align} A+B &amp;= \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} +  \begin{bmatrix} 	b_{11} &amp; b_{12} &amp; b_{13} \\
 b_{21} &amp; b_{22} &amp; b_{23} \end{bmatrix} \\
                 &amp;= \begin{bmatrix}  a_{11}+b_{11} &amp; a_{12}+b_{12} &amp; a_{13}+b_{13} \\
 a_{21}+b_{21} &amp; a_{22}+b_{22} &amp; a_{23}+b_{23}	
 \end{bmatrix} \\
                 &amp;= \begin{bmatrix} 	b_{11}+a_{11} &amp; b_{12}+a_{12} &amp; b_{13}+a_{13} \\
 b_{21}+a_{21} &amp; b_{22}+a_{22} &amp; b_{23}+a_{23} \end{bmatrix} \\
                 &amp;= \begin{bmatrix} 	b_{11} &amp; b_{12} &amp; b_{13} \\
 b_{21} &amp; b_{22} &amp; b_{23} \end{bmatrix} + \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} \\
                 &amp;= B + A.
\end{align}\)      <br />
<br /></li>
  <li>Apakah \(A + (B + C) = (A+B) + C\)?  <br />
Ya karena  <br />
\(\begin{align} A+(B+C) &amp;= \begin{bmatrix} a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} + \left( \begin{bmatrix} b_{11} &amp; b_{12} &amp; b_{13} \\
 b_{21} &amp; b_{22} &amp; b_{23} \end{bmatrix} + \begin{bmatrix} c_{11} &amp; c_{12} &amp; c_{13} \\
 c_{21} &amp; c_{22} &amp; c_{23} \end{bmatrix} \right) \\
                      &amp;= \begin{bmatrix} a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} + \left( \begin{bmatrix} b_{11} + c_{11} &amp; b_{12} + c_{12} &amp; b_{13} + c_{13} \\
 b_{21} + c_{21} &amp; b_{22} + c_{22} &amp; b_{23} + c_{23}	\end{bmatrix} \right) \\
                      &amp;= \begin{bmatrix} a_{11} + b_{11} + c_{11}  &amp; a_{12} + b_{12} + c_{12} &amp; a_{13} + b_{13} + c_{13} \\
 a_{21} + b_{21} + c_{21}  &amp; a_{22} + b_{22} + c_{22} &amp; a_{23} + b_{23} + c_{23} \end{bmatrix} \\
                      &amp;= \begin{bmatrix} a_{11} + b_{11} &amp; a_{12} + b_{12} &amp; a_{13} + b_{13} \\
 a_{21} + b_{21} &amp; a_{22} + b_{22} &amp; a_{23} + b_{23} \end{bmatrix} + \begin{bmatrix} 	 c_{11} &amp;  c_{12} &amp;  c_{13} \\
 c_{21} &amp; c_{22} &amp; c_{23} \end{bmatrix} \\
                      &amp;= \left( \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} + \begin{bmatrix} 	b_{11} &amp; b_{12} &amp; b_{13} \\
 b_{21} &amp; b_{22} &amp; b_{23}	  \end{bmatrix} \right) + \begin{bmatrix} 	c_{11} &amp; c_{12} &amp; c_{13} \\
 c_{21} &amp; c_{22} &amp; c_{23}	  \end{bmatrix} \\
                      &amp;= (A+B)+C.
  \end{align}\)   <br />
<br /></li>
  <li>Apakah \(V\) mempunyai <strong>matriks nol</strong> \(\textbf{0}\) sedemikian sehingga untuk setiap matriks \(A\) di \(V\), \(A + \textbf{0} = A\)?  <br />
Ada, matriks \(\mathbf{0}\) tersebut adalah  <br />
\(\begin{bmatrix} 0 &amp; 0 &amp; 0 \\
     0 &amp; 0 &amp; 0 \end{bmatrix}\) karena
     \(A + \mathbf{0} = \begin{bmatrix} a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} + \begin{bmatrix} 0 &amp; 0 &amp; 0 \\
     0 &amp; 0 &amp; 0 \end{bmatrix} = \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} = A.\)  <br />
<br /></li>
  <li>Untuk setiap matriks \(A\) di dalam \(V\), apakah \(V\) mempunyai matriks yang dilambangkan dengan \(-A\) sedemikian sehingga \(A + (-A) = \mathbf{0}\)? <br />
Ada, matriks \(-A\) tersebut adalah 
\(\begin{bmatrix} -a_{11} &amp; -a_{12} &amp; -a_{13} \\
 -a_{21} &amp; -a_{22} &amp; -a_{23} \end{bmatrix}\)	karena
 \(\begin{align} A + (-A) &amp;= \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} + \begin{bmatrix} 	-a_{11} &amp; -a_{12} &amp; -a_{13} \\
 -a_{21} &amp; -a_{22} &amp; -a_{23} \end{bmatrix} \\
                           &amp;= \begin{bmatrix} 	a_{11}-a_{11} &amp; a_{12}-a_{12} &amp; a_{13}-a_{13} \\
 a_{21}-a_{21} &amp; a_{22}-a_{22} &amp; a_{23}-a_{23} \end{bmatrix} \\
                           &amp;= \begin{bmatrix} 		0 &amp; 0 &amp; 0 \\
     0 &amp; 0 &amp; 0 \end{bmatrix} \\
                           &amp;= \mathbf{0}.
 \end{align}\)	<br />
<br /></li>
  <li>Apakah \(kA\) juga ada di dalam \(V\)?  <br />
Ya, karena
\(kA = k \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23}
 \end{bmatrix} = \begin{bmatrix} 	ka_{11} &amp; ka_{12} &amp; ka_{13} \\
 ka_{21} &amp; ka_{22} &amp; ka_{23} \end{bmatrix}.\)  <br />
<br />
\(\begin{bmatrix} 	ka_{11} &amp; ka_{12} &amp; ka_{13} \\
 ka_{21} &amp; ka_{22} &amp; ka_{23} \end{bmatrix}\) adalah matriks berukuran \(2 \times 3\) sehingga \(cA\) juga berada di dalam \(V\). <br />
<br /></li>
  <li>Apakah \(k(A+B) = kA + kB\)?  <br />
Ya karena <br />
\(\begin{align} k(A+B) &amp;= k \left( \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13} \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} + \begin{bmatrix} 	b_{11} &amp; b_{12} &amp; b_{13} \\
 b_{21} &amp; b_{22} &amp; b_{23} \end{bmatrix} \right) \\
                     &amp;= k \left( \begin{bmatrix} 	a_{11} + b_{11} &amp; a_{12} + b_{12} &amp; a_{13} + b_{13} \\
 a_{21} + b_{21} &amp; a_{22} + b_{22} &amp; a_{23} + b_{23} \end{bmatrix} \right) \\
                     &amp;= \begin{bmatrix} 	k(a_{11} + b_{11}) &amp; k(a_{12} + b_{12}) &amp; k(a_{13} + b_{13}) \\
 k(a_{21} + b_{21}) &amp; k(a_{22} + b_{22}) &amp; k(a_{23} + b_{23}) \end{bmatrix} \\
                     &amp;= \begin{bmatrix} 	ka_{11} + kb_{11} &amp; ka_{12} + kb_{12} &amp; ka_{13} + kb_{13} \\
 ka_{21} + kb_{21} &amp; ka_{22} + kb_{22} &amp; ka_{23} + kb_{23} \end{bmatrix} \\
                     &amp;= \begin{bmatrix} 	ka_{11} &amp; ka_{12} &amp; ka_{13}  \\
 ka_{21} &amp; ka_{22} &amp; ka_{23}  \end{bmatrix} + \begin{bmatrix} 	kb_{11} &amp; kb_{12} &amp; kb_{13} \\
 kb_{21} &amp; kb_{22} &amp; kb_{23} \end{bmatrix} \\
                     &amp;= k \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13}  \\
 a_{21} &amp; a_{22} &amp; a_{23}  \end{bmatrix} + k \begin{bmatrix} 	b_{11} &amp; b_{12} &amp; b_{13}  \\
 b_{21} &amp; b_{22} &amp; b_{23}  \end{bmatrix} \\
                     &amp;= kA + kB.
\end{align}\)  <br />
<br /></li>
  <li>Apakah \((k+l)A = kA + lA\)?  <br />
Ya karena  <br />
\(\begin{align} (k+l) A &amp;= (k+l) \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13}  \\
 a_{21} &amp; a_{22} &amp; a_{23} \\ 		
\end{bmatrix}  \\
                      &amp;= \begin{bmatrix} (k+l) a_{11} &amp; (k+l) a_{12} &amp; (k+l) a_{13}  \\
 (k+l) a_{21} &amp; (k+l) a_{22} &amp; (k+l) a_{23} 	 \end{bmatrix} \\
                      &amp;= \begin{bmatrix} 	k a_{11} + l a_{11} &amp; k a_{12} + l a_{12} &amp; k a_{13} + l a_{13}  \\
 k a_{21} + l a_{21} &amp; k a_{22} + l a_{22} &amp; k a_{23} + l a_{23} 	\end{bmatrix} \\
                      &amp;= \begin{bmatrix} 	k a_{11} &amp; k a_{12}  &amp; k a_{13}   \\
 k a_{21} &amp; k a_{22}  &amp; k a_{23}  \end{bmatrix} + \begin{bmatrix} 	l a_{11} &amp; l a_{12} &amp; l a_{13}  \\
 l a_{21} &amp; l a_{22} &amp; l a_{23} \end{bmatrix} \\
                      &amp;= k \begin{bmatrix} 	a_{11} &amp; a_{12}  &amp; a_{13}   \\
 a_{21} &amp; a_{22}  &amp; a_{23} \end{bmatrix} + l \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13}  \\
 a_{21} &amp; a_{22} &amp; a_{23} 	\end{bmatrix} \\
                      &amp;= kA + lA.
\end{align}\)  <br />
<br /></li>
  <li>Apakah \(k(lA) = (kl)A\)? <br />
Ya karena <br />
\(\begin{align} k(l A) &amp;= k \left( l \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13}  \\
 a_{21} &amp; a_{22} &amp; a_{23}  \end{bmatrix} \right)  \\
                    &amp;= k \left( \begin{bmatrix} 	l a_{11} &amp; l a_{12} &amp; l a_{13}  \\
 l a_{21} &amp; l a_{22} &amp; l a_{23} \end{bmatrix} \right)  \\
                    &amp;= k \begin{bmatrix} 	l a_{11} &amp; l a_{12} &amp; l a_{13}  \\
 l a_{21} &amp; l a_{22} &amp; l a_{23} \end{bmatrix}  \\
                    &amp;= \begin{bmatrix} 	kl a_{11} &amp; kl a_{12} &amp; kl a_{13}  \\
 kl a_{21} &amp; kl a_{22} &amp; kl a_{23} \end{bmatrix} \\
                    &amp;= \begin{bmatrix} 	(kl)a_{11} &amp; (kl)a_{12} &amp; (kl)a_{13}  \\
 (kl)a_{21} &amp; (kl)a_{22} &amp; (kl)a_{23} \end{bmatrix} \\
                    &amp;= (kl) \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13}  \\
 a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} \\
                    &amp;= (kl) A. 
\end{align}\) <br />
<br /></li>
  <li>Apakah \(1(A) = A\)? <br />
Ya karena  <br />
\(\begin{align} 1(A) &amp;= 1 \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13}  \\
a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix} \\
                  &amp;= \begin{bmatrix} 	1a_{11} &amp; 1a_{12} &amp; 1a_{13}  \\
1a_{21} &amp; 1a_{22} &amp; 1a_{23} \end{bmatrix} \\
                  &amp;= \begin{bmatrix} 	a_{11} &amp; a_{12} &amp; a_{13}  \\
a_{21} &amp; a_{22} &amp; a_{23} \end{bmatrix}  \\
                  &amp;= A.
\end{align}\)  <br />
<br /></li>
</ol>

<p>Karena \(V\) memenuhi 10 aksioma dari definisi suatu ruang vektor, \(V\) atau himpunan dari semua matriks berukuran \(2 \times 3\) beserta operasi <em>matrix addition</em> dan <em>scalar multiplication</em> merupakan sebuah <strong>ruang vektor</strong>.   \(\square\)</p>]]></content><author><name>Hendra Bunyamin</name><email>hendra.bunyamin@it.maranatha.edu</email></author><category term="linear algebra" /><category term="vector space" /><category term="matrix" /><summary type="html"><![CDATA[Sepuluh aksioma digunakan untuk membuktikan suatu Ruang Vektor.]]></summary></entry></feed>